Training data your models can rely on.
Saarve AI is a managed workforce for data annotation, RLHF and model evaluation. A trained Nairobi team, layered quality review, and the flexibility to scale with your roadmap.
- Layered QAAnnotator, reviewer and QA lead on every project
- Tool-agnosticCVAT, Labelbox, Encord-style platforms or your own tools
- Free pilot firstSee the quality on your data before you commit
- Time-zone overlapWorking hours shared with Europe and the Middle East
Every data type your models learn from.
From pixel-level vision work to human judgment on model outputs, one managed team handles labelling, review and re-work against your guidelines.
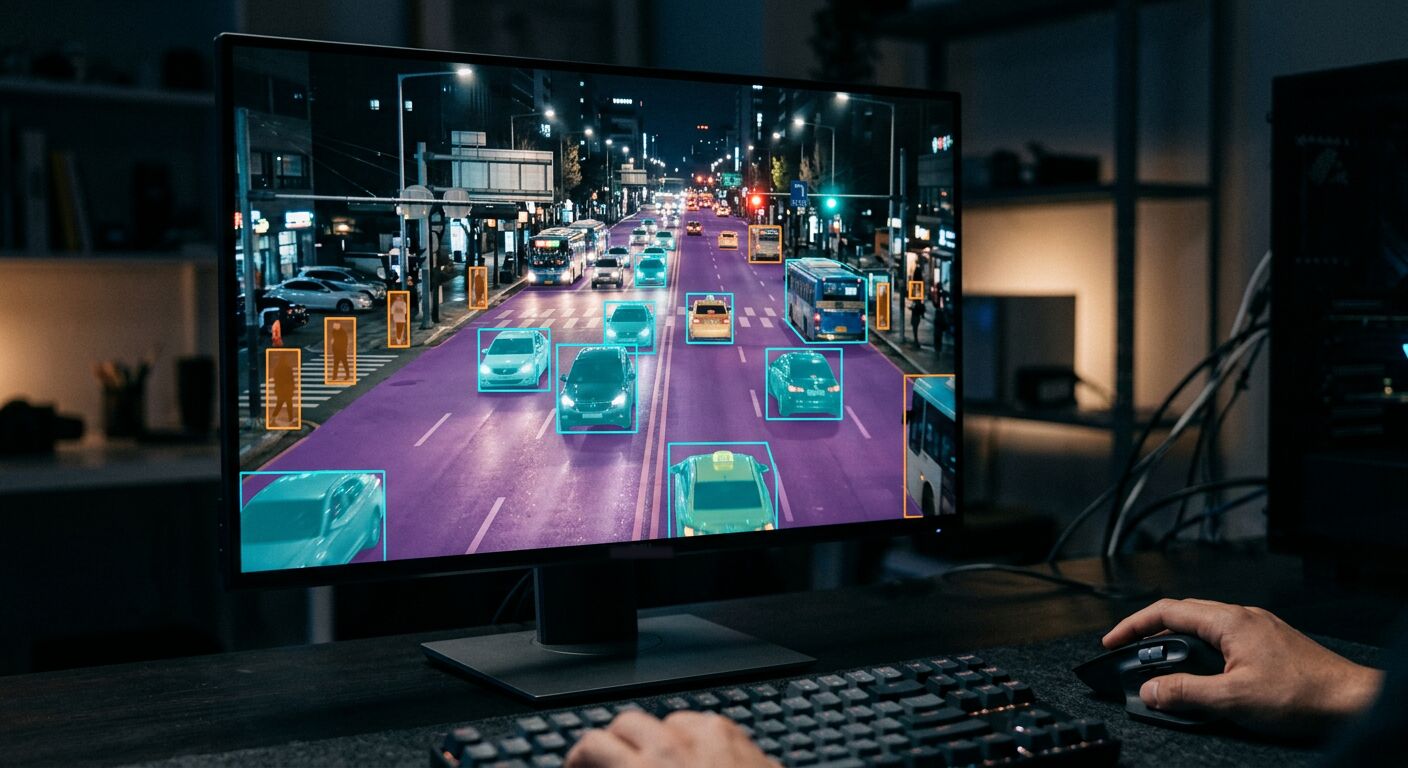
Computer vision annotation
Precise labels for images, video and 3D sensor data.
Video slicing & clip segmentation
Long footage cut into labelled, time-stamped clips and events, ready for training.
NLP, text & audio
Language data labelled by people who read and hear it fluently.
RLHF & model evaluation
Human judgment that shapes and tests LLM and multimodal behaviour.
Data collection
Targeted collection to fill the gaps in your training and evaluation sets.
QA & dataset review
Audits and re-labelling of existing datasets, with clear error reporting so you know what changed.
Built for the problems AI teams are solving now.
The same trained team and QA process, applied to the data behind your product.
Autonomous vehicles & robotics
Perception models need consistent labels across frames, cameras and sensors. We annotate road scenes, warehouse and field footage, and 3D point clouds so objects are tracked reliably through every sequence.
Typical work
- Bounding boxes and segmentation on driving scenes
- Object tracking across video sequences
- LiDAR and 3D point cloud labelling
- Keypoints for pose and manipulation
Generative AI & LLMs
Trained raters compare, grade and stress-test model outputs against your rubric, so you get human signal you can use for fine-tuning and release decisions.
Typical work
- Preference ranking for RLHF
- Rubric-based response grading
- Red-teaming and safety review
- Swahili and other African-language evaluation
Geospatial & drones
Aerial and satellite imagery is dense and detail-heavy. We outline structures, land use and assets precisely, with review steps that catch the small misses.
Typical work
- Polygon outlines of buildings and land parcels
- Semantic segmentation of terrain and land cover
- Object detection on drone footage
Agriculture
Crops, pests and livestock vary by season and region. Our team labels field imagery with care for the edge cases that make agricultural models hard.
Typical work
- Crop and weed segmentation
- Plant, fruit and pest detection
- Livestock counting and tracking
Retail & video analytics
Hours of store, shelf or camera footage turned into structured events and labelled clips your models can learn from.
Typical work
- Video slicing and event segmentation
- Product and shelf detection
- People and object tracking
Healthcare & speech
Speech and text data handled under NDA with access controls, transcribed and labelled to your guidelines, including Swahili and other African languages.
Typical work
- Audio transcription and translation
- Named entity recognition in text
- Text and document classification
Quality built in layers, not inspected at the end.
Every task moves through three roles before it reaches you. Errors are caught close to where they happen, fed back to the team, and reported to you on a regular schedule.
- 01
Annotator
A trained team member labels each item against your guidelines, raising unclear cases instead of guessing.
- 02
Reviewer
A second, more experienced person checks the work, corrects errors and sends feedback to the annotator.
- 03
QA lead
The QA lead audits batches, keeps guideline interpretation consistent across the team and owns the quality report you receive.
Human judgment for generative AI.
Fluent, trained raters who follow your rubric closely and flag what the rubric does not cover.
- Preference ranking
- Side-by-side comparisons of model responses for reward modelling.
- Rubric grading
- Consistent scoring against the criteria you define.
- Red-teaming
- Probing models for failures, gaps and unsafe behaviour.
- Safety review
- Reviewing outputs for harmful or policy-breaking content.
From first sample to full production.
No long sales cycle. You see the work on your own data before deciding anything.
- 01
Share a sample & guidelines
Send a small batch of your data and your labelling instructions, in your tool or ours.
- 02
Free sample analysis / pilot
We label the sample, check it against your spec and agree on scope, turnaround and pricing.
- 03
Scale with a managed team
A dedicated team with layered QA and regular quality reporting, scaling up or down as volume changes.
We work in your stack.
Our annotators are experienced across the major labelling platforms and comfortable inside client-built tools. No migration, no new software to buy.
- CVAT
- Labelbox
- Encord-style platforms
- Your in-house tools
Your data, handled with care.
How we protect client data on every engagement.
- Work under NDA. Confidentiality agreements are in place before any data is shared.
- Access controls. Access to project data is restricted and controlled throughout the engagement.
- Your environment, if you prefer. We can work directly inside your own labelling tools.
Building skilled, fairly paid digital work in Kenya.
We want talented people in Kenya to build real, skilled careers in the AI economy, working directly with the teams that build the models.
Every project you run with us is done by a trained, managed Nairobi team, and supports that mission. We believe that care shows up in the quality of your data.
Clear, competitive pricing.
Per-object pricing for vision work, hourly for NLP and RLHF. Final rates depend on task complexity and are confirmed after your pilot.
Managed annotation teams
Dedicated, managed teams for vision, video, text and audio work, with layered QA included.
RLHF raters & evaluators
Preference ranking, rubric grading, red-teaming and safety review.
Computer vision, per object
Priced per object by annotation type and complexity.
NLP, text & audio
Classification, NER, transcription and translation, billed hourly.
Every engagement starts with a free pilot.
Ask for a quoteSee the quality on your own data.
Tell us about your data and what you need labelled or evaluated. We'll reply with next steps and a pilot plan.
- We review your request and ask for a sample and guidelines.
- We run a free pilot and share the results with you.
- You decide whether to scale, with a clear quote.